Newsletter Subscribe
Enter your email address below and subscribe to our newsletter
[forminator_form id="25163"]

All voices matter
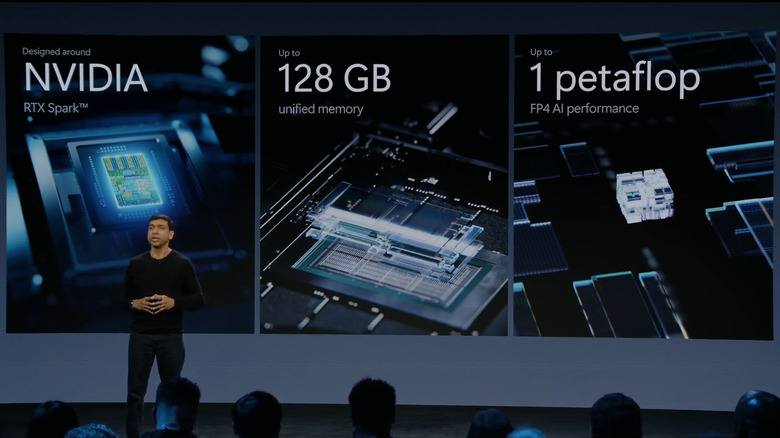
cnet+1.pasqualepillitteri.cnet+1.Microsoft said on Wednesday, Oct. 7, that open-weight AI models from DeepSeek and Nvidia will run locally on Windows PCs. The company made the announcement at its Windows and Surface event in San Francisco. The plan is part of what Microsoft calls "hybrid intelligence," where some AI work runs on the device and some in the cloud. It was the company's first laptop-focused event in more than two years.cnet+2
Windows chief Pavan Davuluri said local AI will "shape the next chapter of the PC," according to CNET. A slide shown on stage said DeepSeek V4 Flash, a model with 284 billion parameters, can run in 60 GB of memory once it is compressed, or quantized, to 1.6 bits per parameter.bgr+3
Microsoft described DeepSeek V4 Flash as offering "near-frontier intelligence in 60GB of memory," according to slides from the official livestream. Nvidia calls it a mixture-of-experts model with 13 billion active parameters. Reuters reported that the V4 model can run on machines with at least 60 GB of memory and can beat OpenAI's GPT-5 on some coding and reasoning tasks.reuters+1
Nvidia will also release a new local Nemotron model with more than 70 billion parameters and "powerful agentic capabilities" on Oct. 15. The keynote slides did not give the model's exact name. SlashGear reported that both Nemotron and DeepSeek V4 Flash will work with the Windows ML runtime. Microsoft also said llama.cpp, a popular open-source inference engine, is coming to Windows ML, with high-level APIs for building generative AI apps. It has not given a release date.pasqualepillitteri+1
There were other AI announcements too:
cnetslashgear+1inshorts+1The models are aimed at PCs with Nvidia's RTX Spark chip, which can have up to 128 GB of unified memory. The new Surface Laptop Ultra uses that chip. It starts at $2,599, preorders are open, and it ships Friday, Oct. 16, according to CNET. Reuters reported that the event marked years of work between Microsoft and Nvidia to move tasks like writing code off the cloud and onto desktops and laptops.pasqualepillitteri+2
The 1.6-bit compression is what makes it work. At 4 bits, DeepSeek V4 Flash's weights would take about 142 GB, more than any RTX Spark machine has. Heavy compression can also lower a model's quality, and "near-frontier" is Microsoft's own claim. No outside group has tested it yet.pasqualepillitteri